|
Joy Yingqing He (何盈庆) Bio
I am a researcher working on computer vision, video foundation models and interactive world modeling. My research spans video pre-training and post-training, controllable and multimodal generation, long-form video generation, and agentic video systems. My long-term goal is to build intelligent agent that can understand, simulate, and interact with dynamic visual worlds.
Google Scholar (3k+ Citations) /
Github (10k+ Stars) / |
|
News
- [01/2026] 1 paper was accepted to ICLR 2026. |
Talks
|
Awards
|
Publications / Research Projects |
|
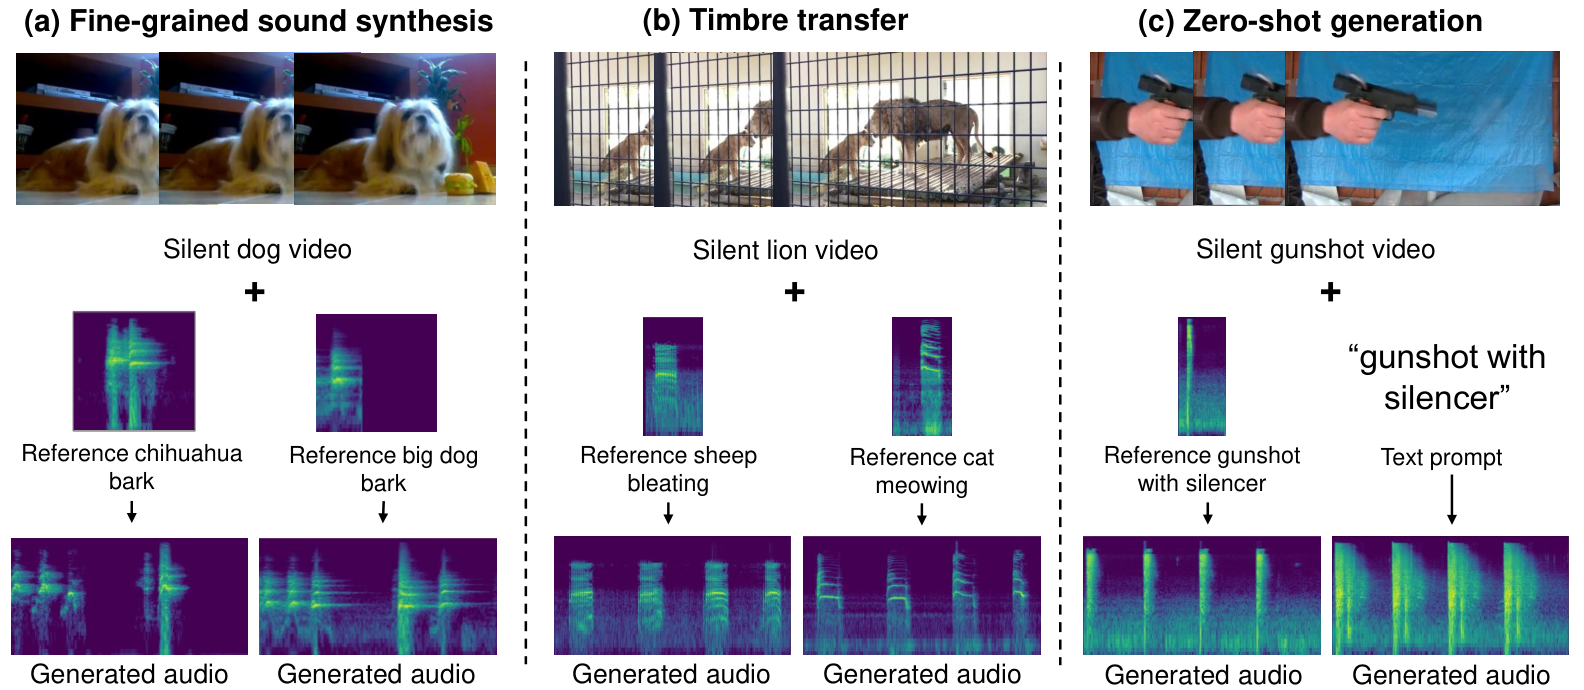
AC-Foley: Reference-Audio-Guided Video-to-Audio Synthesis with Acoustic Transfer
Pengjun Fang, Yingqing He, Yazhou Xing, Qifeng Chen, Ser-Nam Lim, Harry Yang ICLR 2026 Project Page / Paper / Github AC-Foley is a reference-audio-guided video-to-audio model that transfers acoustic attributes from reference audio for fine-grained Foley generation, timbre transfer, and zero-shot sound synthesis. |
|
VideoTuna: A Powerful Toolkit for Video Generation with Model Fine-Tuning and Post-Training
Yingqing He, Yazhou Xing, Zhefan Rao, Haoyu Wu, Zhaoyang Liu, Jingye Chen, Pengjun Fang, Jiajun Li, Liya Ji, Runtao Liu, Xiaowei Chi, Yang Fei, Guocheng Shao, Yue Ma, Qifeng Chen Github, 2024 Nov Project Page / Github VideoTuna is the first repo that integrates multiple AI video generation models for text-to-video, image-to-video, text-to-image generation for fine-tuning and post-training (to the best of our knowledge). Additionally, VideoTuna provides a comprehensive pipeline in video generation, including pre-training, continuous training, post-training (alignment), and fine-tuning. |
|
VideoVAE+: Large Motion Video Autoencoding with Cross-modal Video VAE
Yazhou Xing*, Yang Fei*, Yingqing He*, Jingye Chen, Jiaxin Xie, Xiaowei Chi, Qifeng Chen ICCV 2025 Project Page / Paper / Github VideoVAE+ is a state-of-the-art Video VAE model that can encode and decode video clips with large motion and high definition. |
|
|
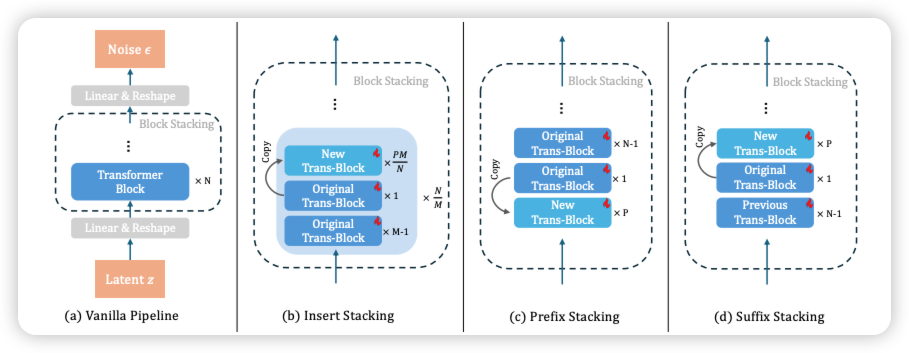
ModelGrow: Continual Text-to-Video Pre-training with Model Expansion and Language Understanding Enhancement
Zhefan Rao*, Liya Ji*, Yazhou Xing, Runtao Liu, Zhaoyang Liu, Jiaxin Xie, Ziqiao Peng, Yingqing He, Qifeng Chen Technical Report, 2024 Dec Project Page / Paper / Github ModelGrow is a method that scales the model capacity and enhances the language understanding of text-to-video models during continous Pre-training. |
|
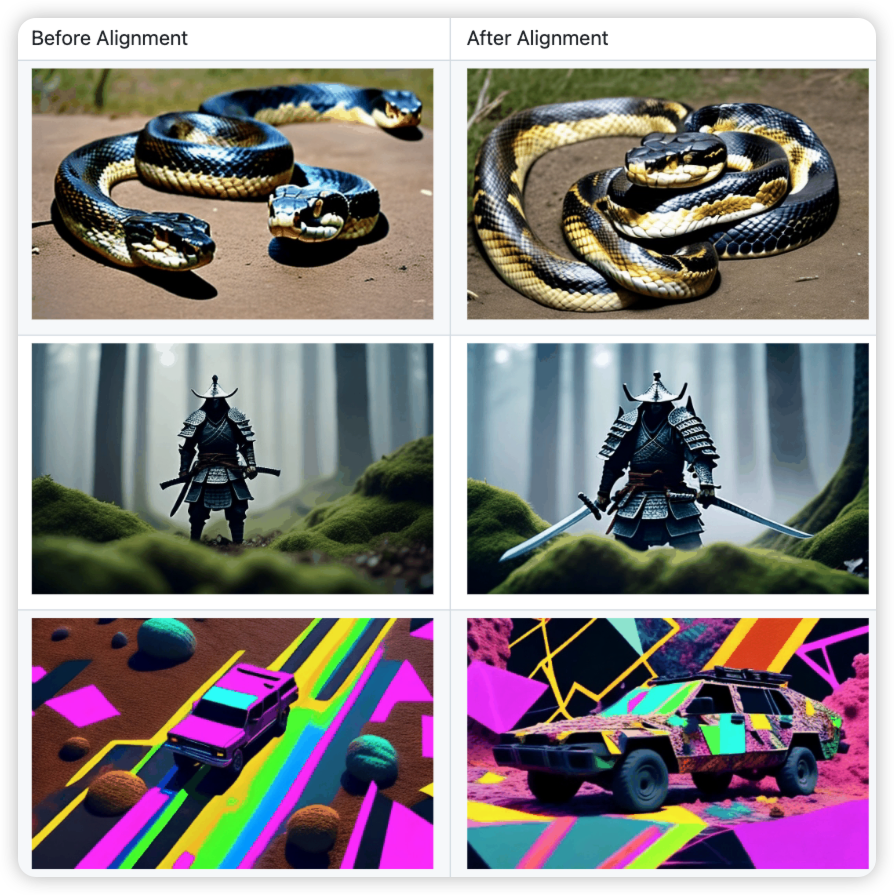
VideoDPO: Omni-Preference Alignment for Video Diffusion Generation
Runtao Liu*, Haoyu Wu*, Ziqiang Zheng, Chen Wei, Yingqing He, Renjie Pi, Qifeng Chen CVPR, 2025 Project Page / Paper / Github
|
|
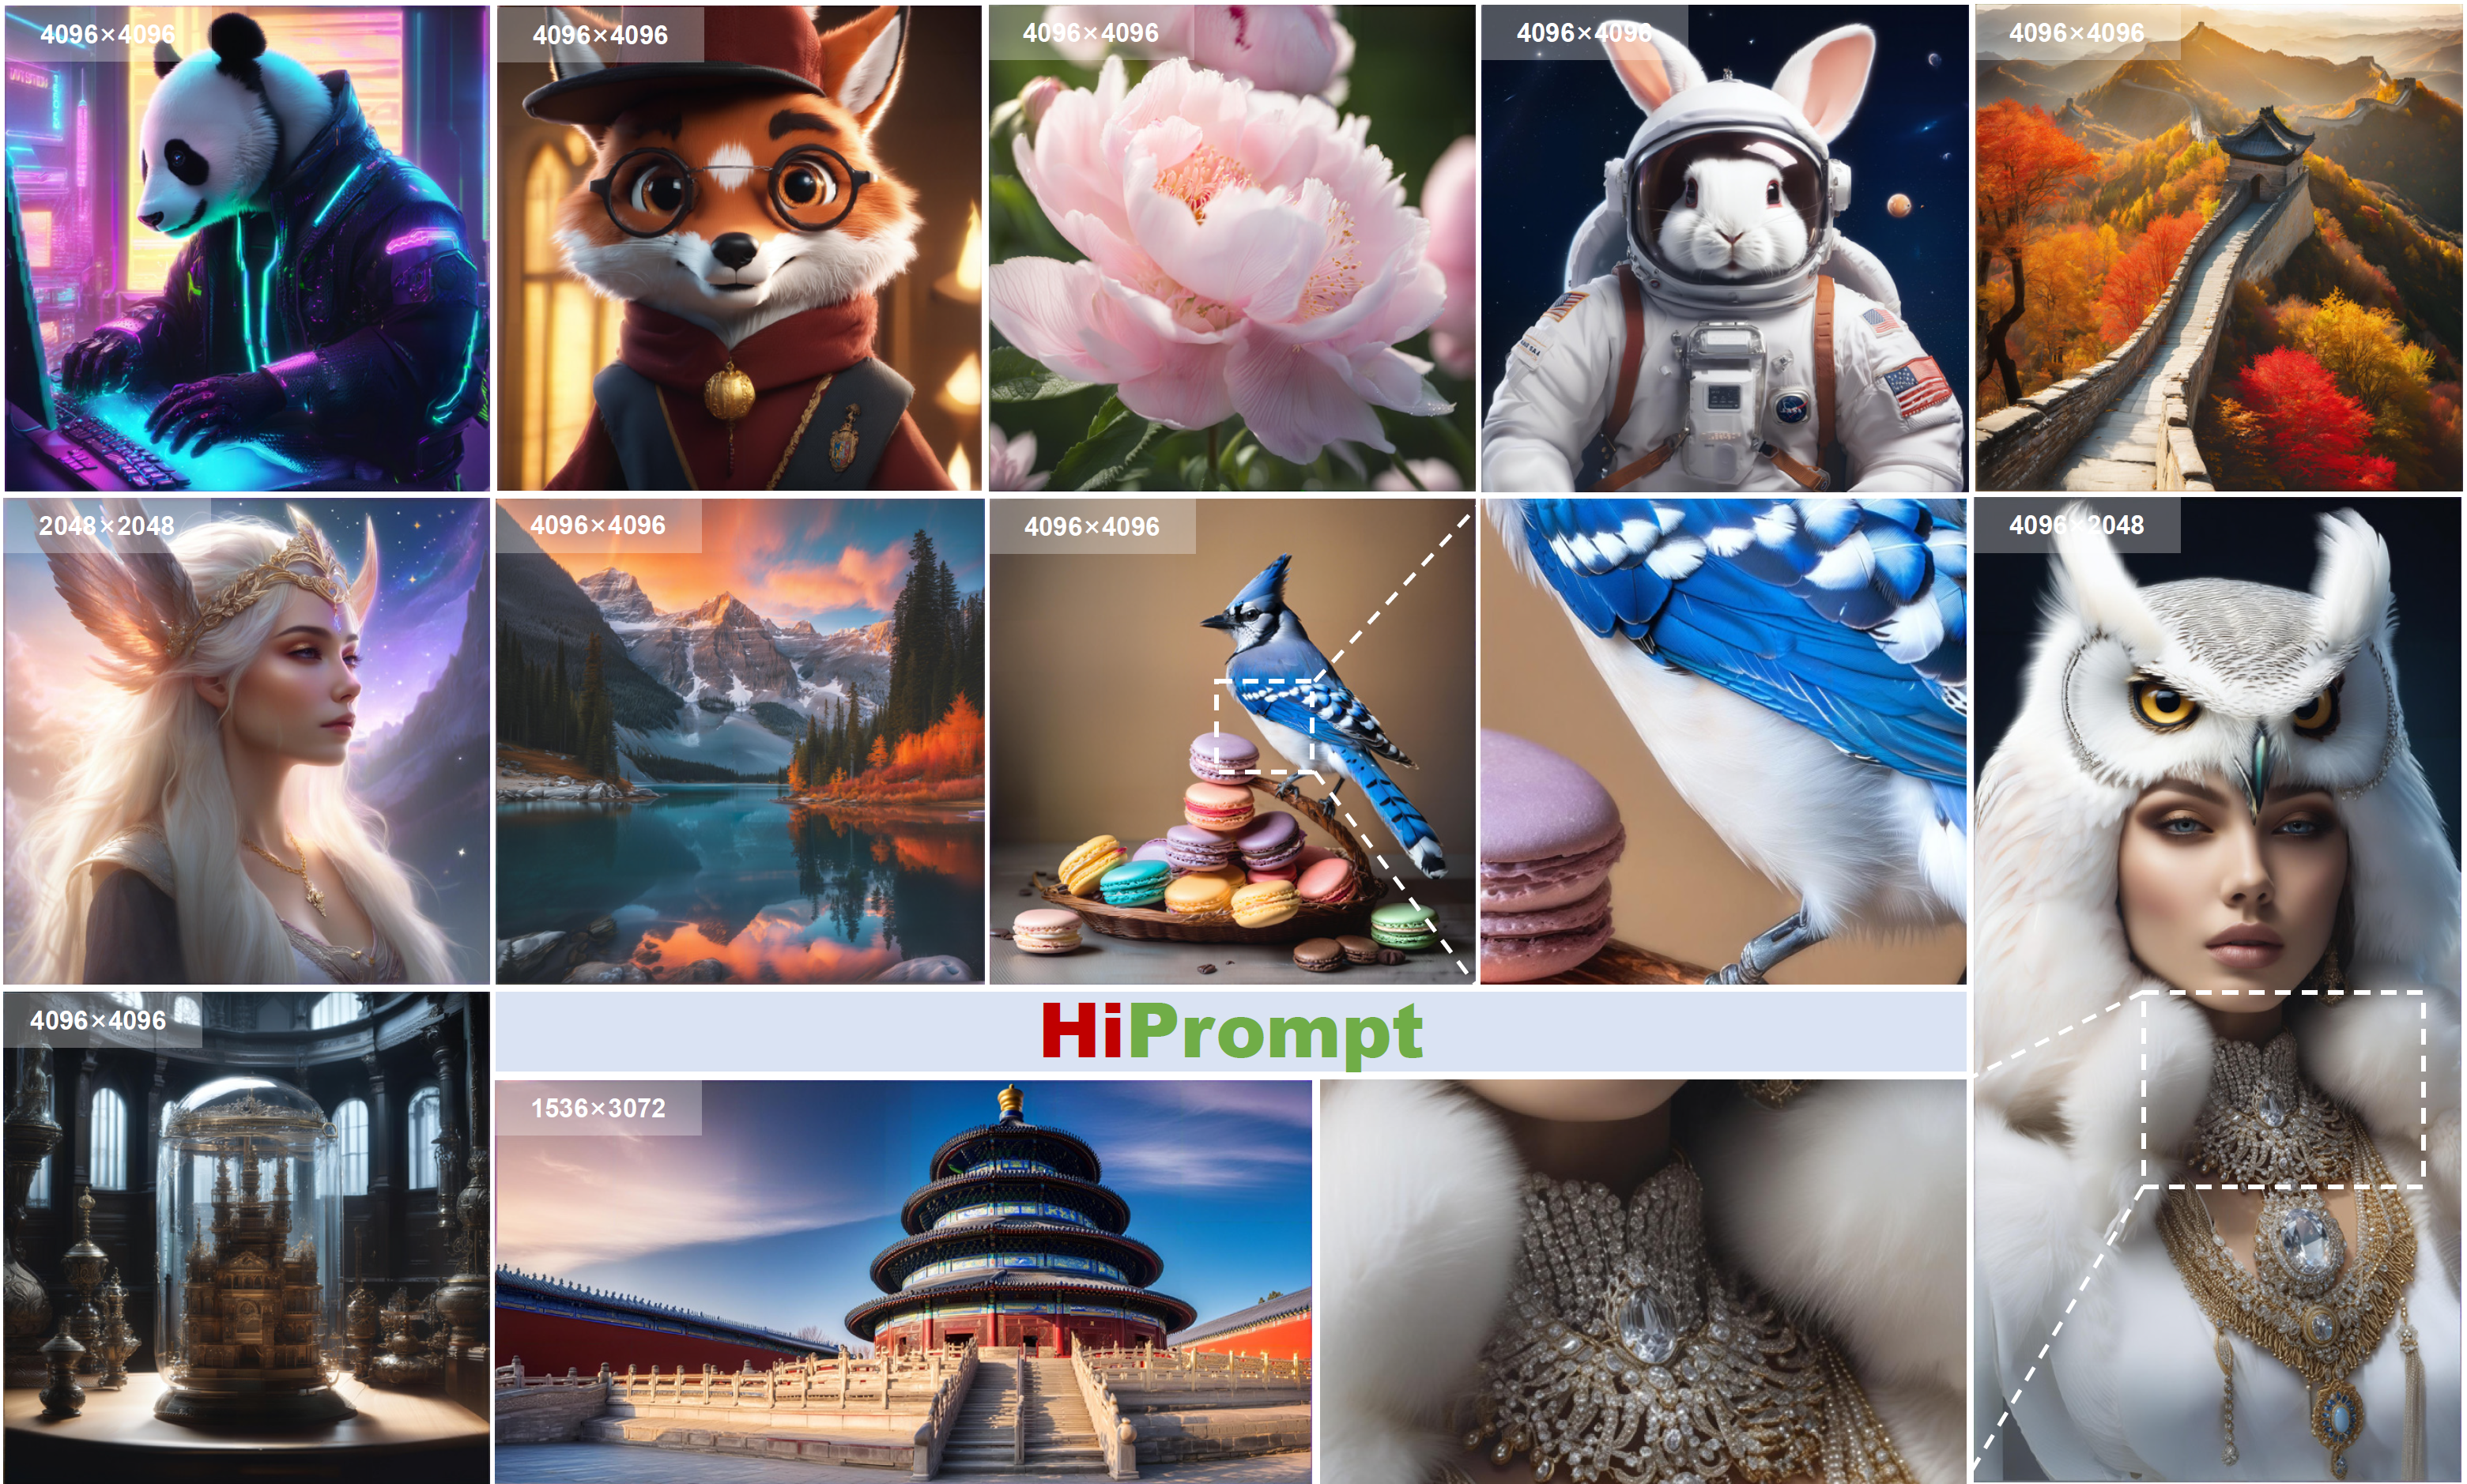
HiPrompt: Tuning-free Higher-Resolution Generation with Hierarchical MLLM Prompts
Xinyu Liu, Yingqing He, Lanqing Guo, Xiang Li, Bu Jin, Peng Li, Yan Li, Chi-Min Chan, Qifeng Chen, Wei Xue, Wenhan Luo, Qifeng Liu, Yike Guo IJCV, 2026 Project Page / Paper / Github
|
|
MMTrail: A Multimodal Trailer Video Dataset with Language and Music Descriptions
Xiaowei Chi, Aosong Cheng, Pengjun Fang, Yatian Wang, Zeyue Tian, Yingqing He, Zhaoyang Liu, Xingqun Qi, Jiahao Pan, Rongyu Zhang, Mengfei Li, Yanbing Jiang, Wei Xue, Wenhan Luo, Qifeng Chen, Shanghang Zhang, Qifeng Liu, Yike Guo Technical Report, 2024 Project Page / Paper / Github MMTrail is a large-scale multi-modality video-language dataset with over 20M trailer clips, featuring high-quality multimodal captions that integrate context, visual frames, and background music, aiming to enhance cross-modality studies and fine-grained multimodal-language model training. |
|
|
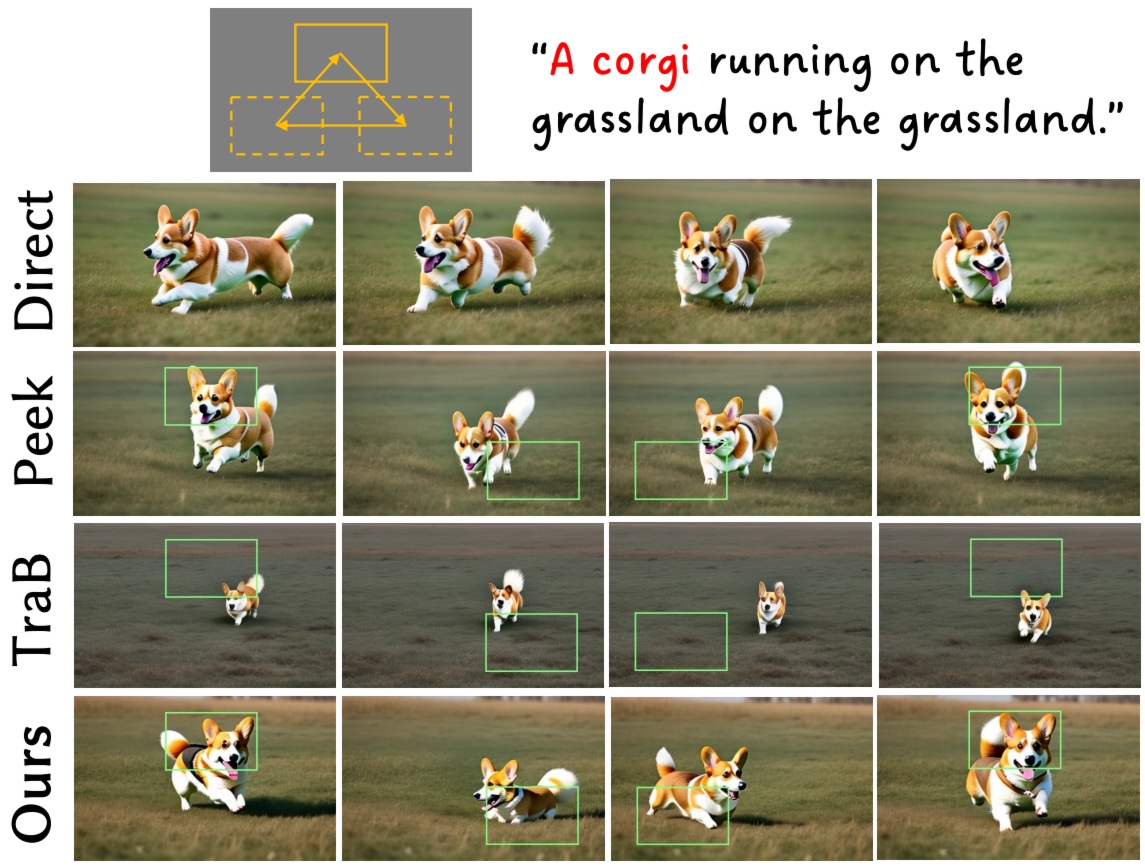
FreeTraj: Tuning-Free Trajectory Control in Video Diffusion Models
Haonan Qiu, Zhaoxi Chen, Zhouxia Wang, Yingqing He, Menghan Xia, Ziwei Liu IJCV, 2026 Project Page / Paper / Github FreeTraj is a tuning-free method for trajectory-controllable video generation based on pre-trained video diffusion models. |
|
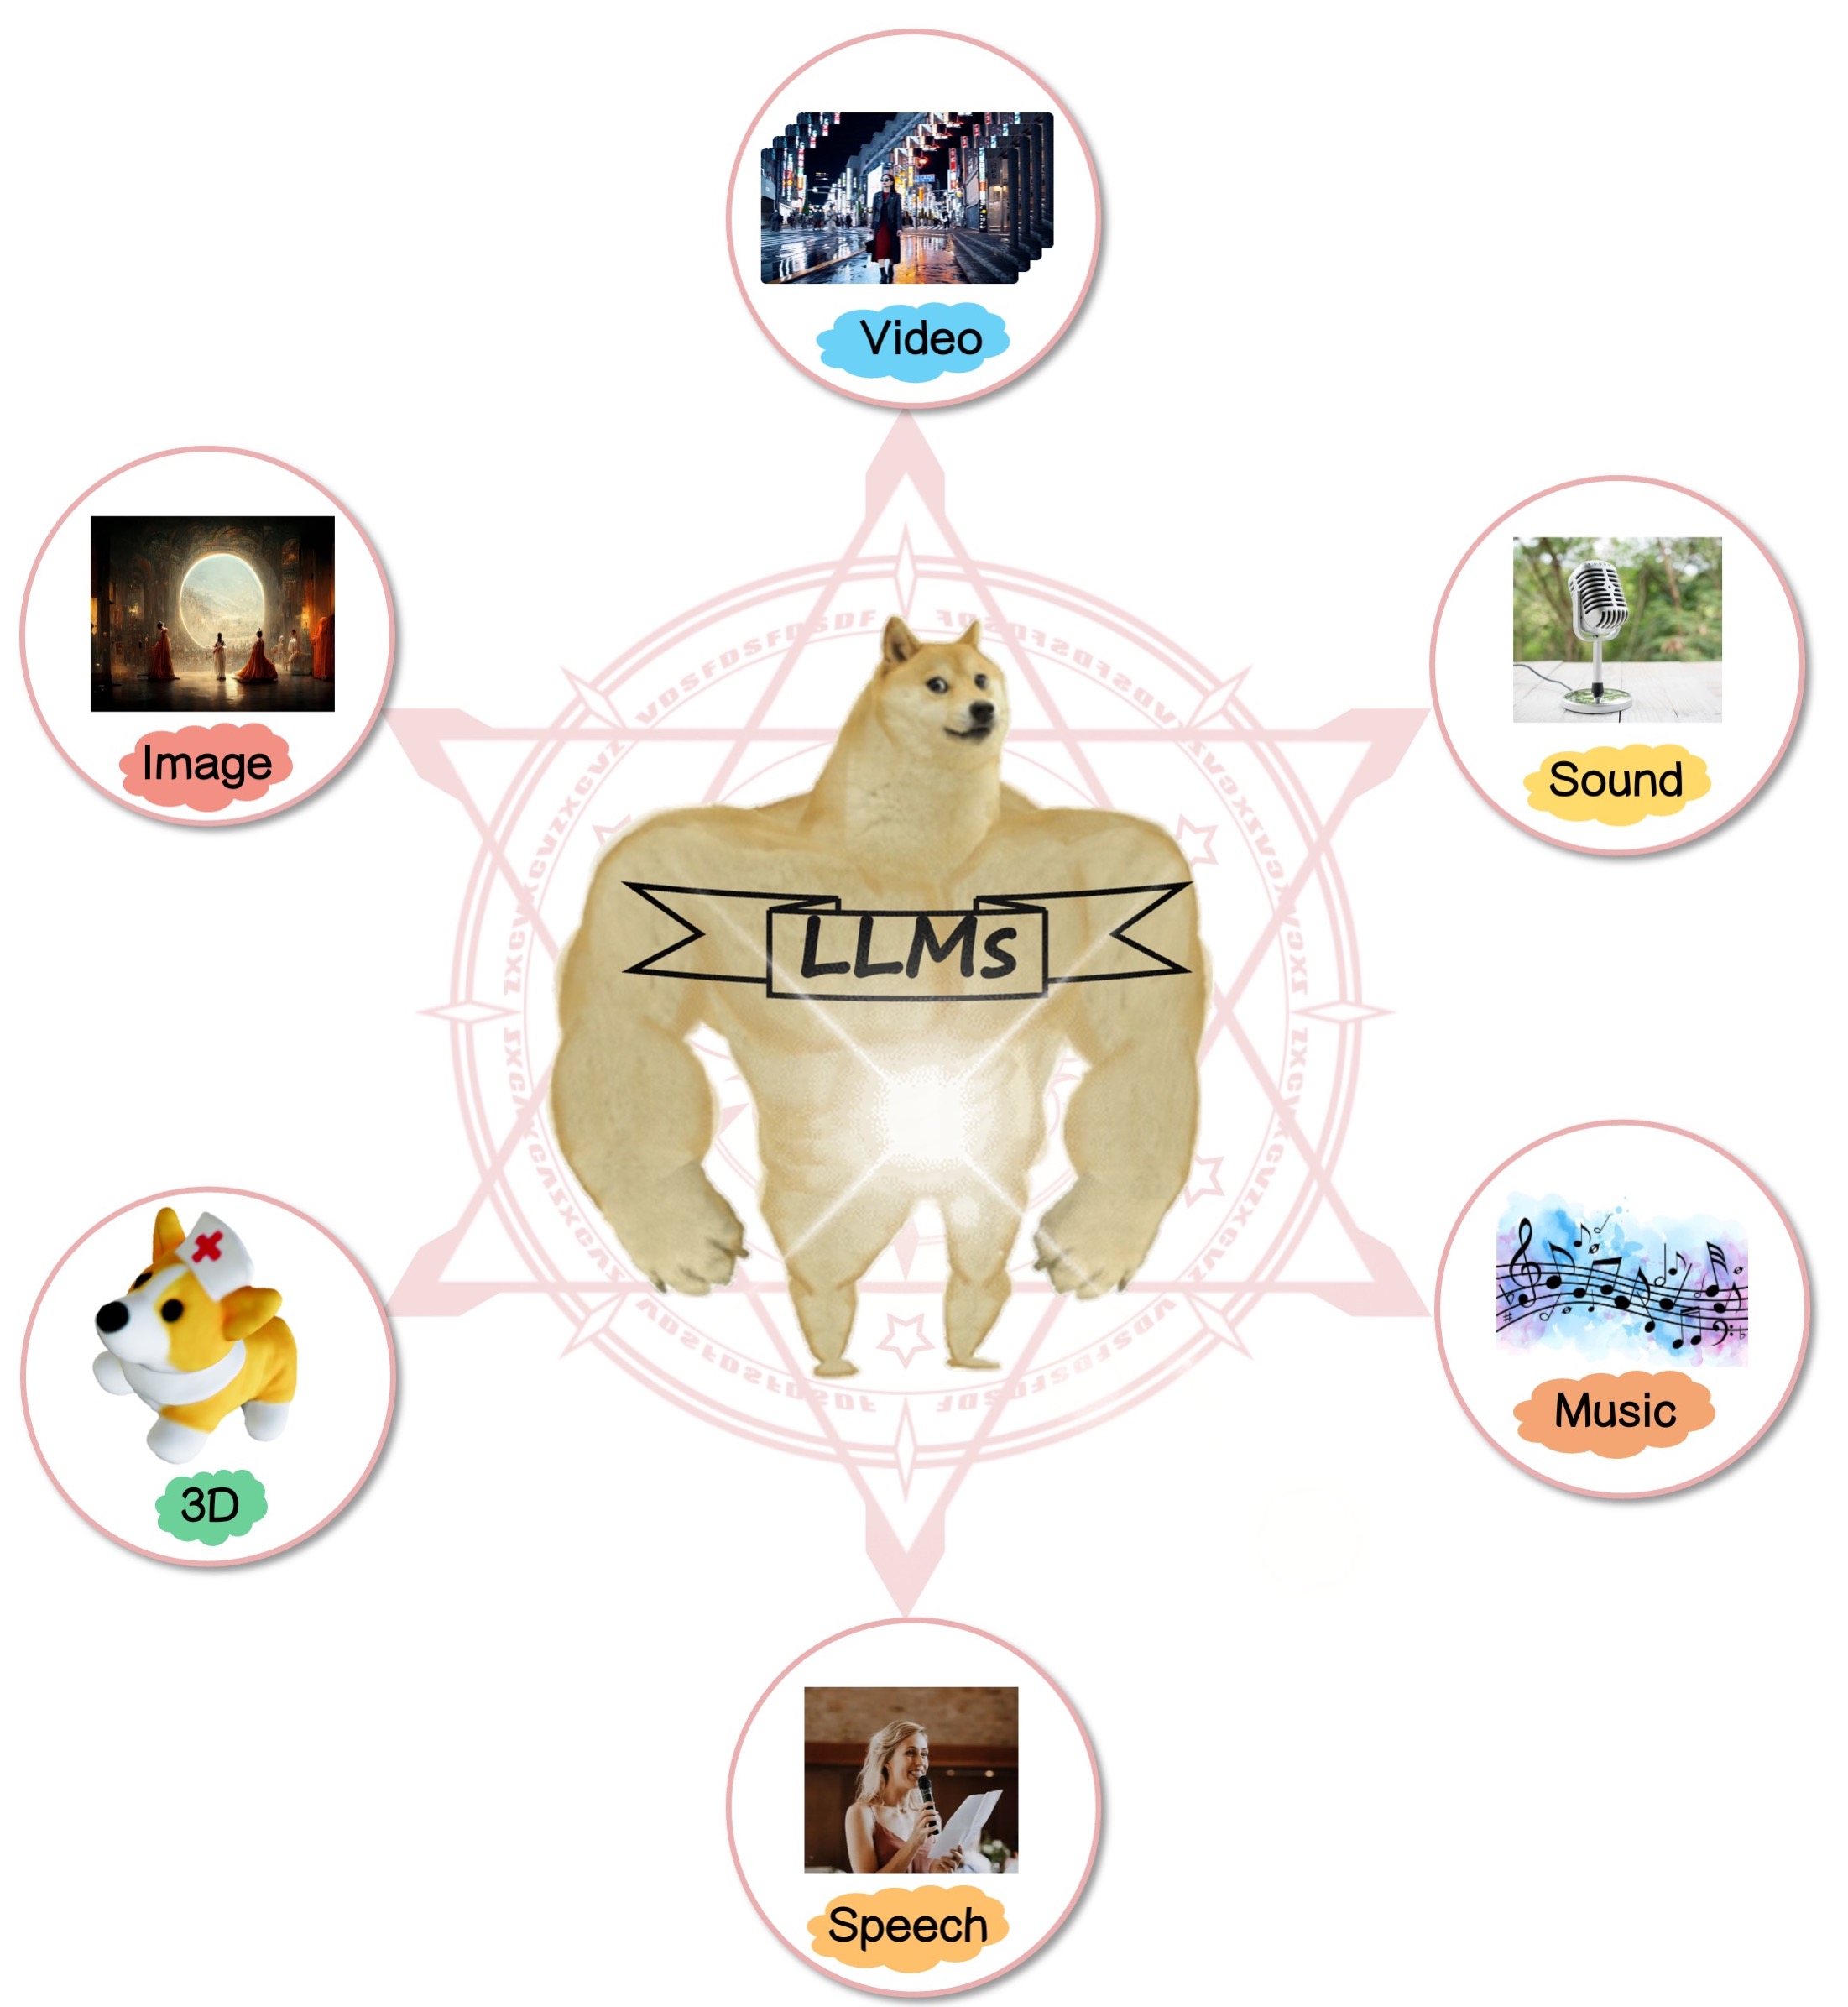
LLMs Meet Multimodal Generation and Editing: A Survey
Yingqing He, Zhaoyang Liu, Jingye Chen, Zeyue Tian, Hongyu Liu, Xiaowei Chi, Runtao Liu, Ruibin Yuan, Yazhou Xing, Wenhai Wang, Jifeng Dai, Yong Zhang, Wei Xue, Qifeng Liu, Yike Guo, Qifeng Chen Technical Report, 2024 Paper / Github This survey includes works of image, video, 3D, and audio generation and editing. We emphasize the roles of LLMs on the generation and editing of these modalities. We also includes works of multimodal agents and generative AI safety. |
|
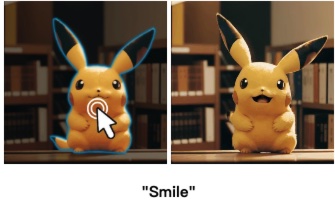
Follow-Your-Click: Open-domain Regional Image Animation via Short Prompts
Yue Ma*, Yingqing He*, Hongfa Wang, Andong Wang, Chenyang Qi, Chengfei Cai, Xiu Li, Zhifeng Li, Heung-Yeung Shum, Wei Liu, Qifeng Chen AAAI, 2025 Project Page / Paper / Github
|
|
Follow-Your-Emoji: Fine-Controllable and Expressive Freestyle Portrait Animation
Yue Ma*, Hongyu Liu*, Hongfa Wang*, Heng Pan*, Yingqing He, Junkun Yuan, Ailing Zeng, Chengfei Cai, Heung-Yeung Shum, Wei Liu, Qifeng Chen SIGGRAPH Asia, 2024 Project Page / Paper / Github
|
|
|
Animate-A-Story: Storytelling with Retrieval-Augmented Video Generation
Yingqing He*, Menghan Xia*, Haoxin Chen*, Xiaodong Cun, Yuan Gong, Jinbo Xing, Yong Zhang, Xintao Wang, Chao Weng, Ying Shan, Qifeng Chen ECCV AI4VA Workshop, 2024 Project Page / Paper / Github A novel story-to-video pipeline with both structure and character controls, facilitating the generation of a vlog for a teddy bear. |
|
|
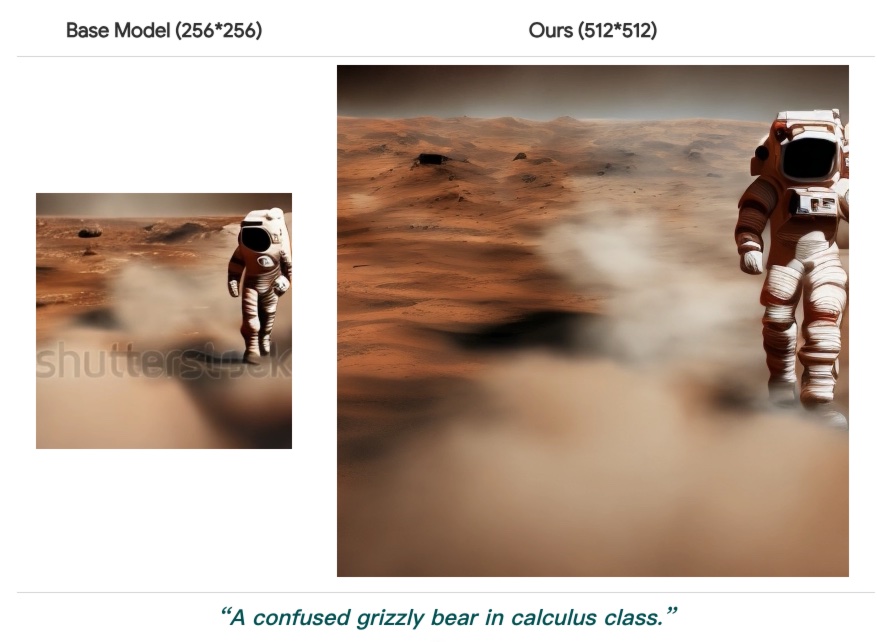
Make a Cheap Scaling: A Self-Cascade Diffusion Model for Higher-Resolution Adaptation
Lanqing Guo*, Yingqing He*, Haoxin Chen, Menghan Xia, Xiaodong Cun, Yufei Wang, Siyu Huang, Yong Zhang, Xintao Wang, Qifeng Chen, Ying Shan, Binhan Wen ECCV, 2024 Project Page / Paper / Github
|
|
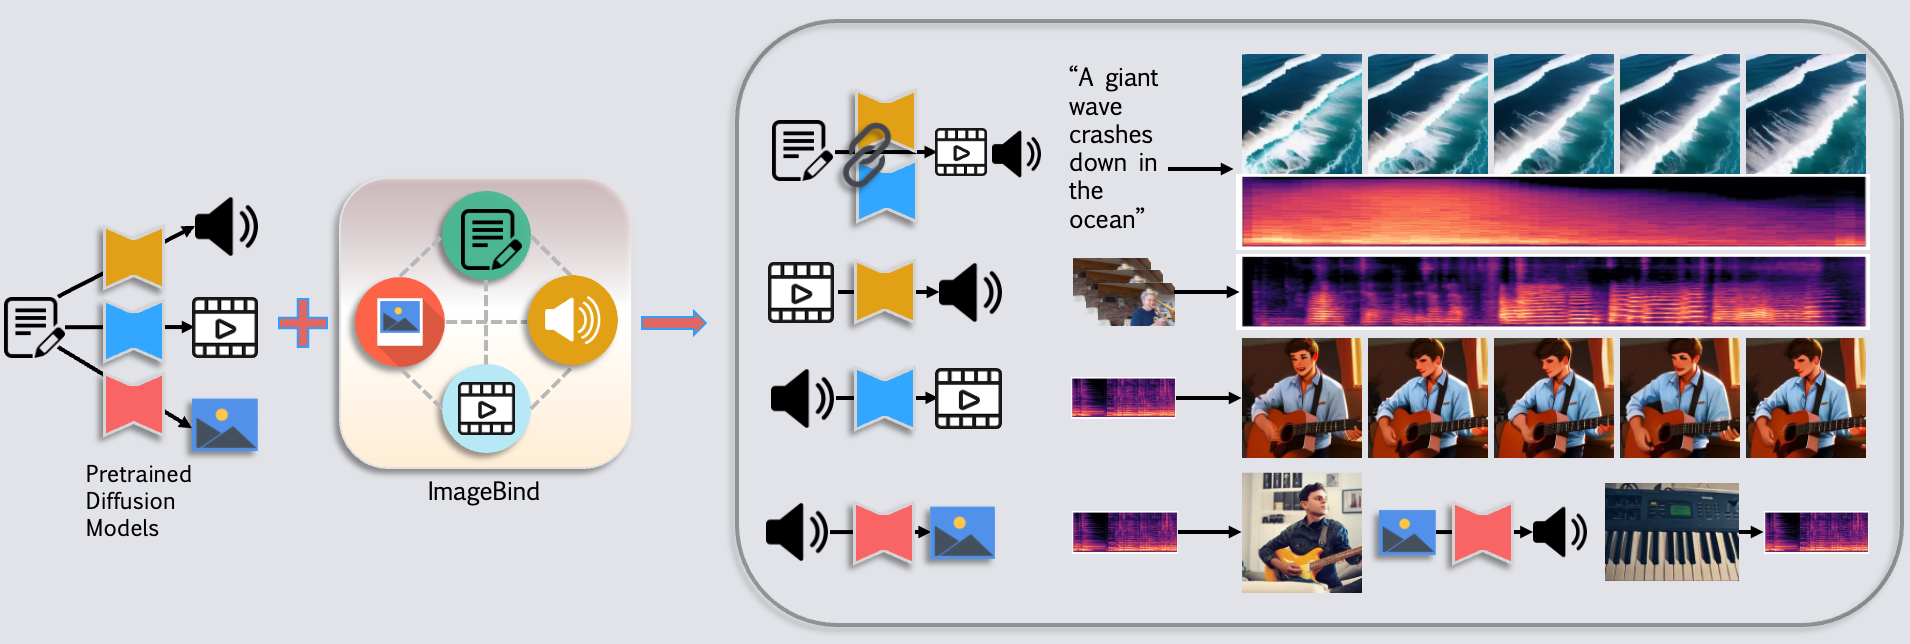
Seeing and Hearing: Open-domain Visual-Audio Generation with Diffusion Latent Aligners
Yazhou Xing*, Yingqing He*, Zeyue Tian*, Xintao Wang, Qifeng Chen CVPR, 2024 Project Page / Paper / Github
|
|
Scalecrafter: Tuning-free higher-resolution visual generation with diffusion models
Yingqing He*, Shaoshu Yang*, Haoxin Chen, Xiaodong Cun, Menghan Xia, Yong Zhang, Xintao Wang, Ran He, Qifeng Chen, Ying Shan ICLR, 2024 (Spotlight) Project Page / Paper / Github Generating 16x higher-resolution images and 4x higher-resolution videos without any extra data and training effort. |
|
|
MagicStick: Controllable Video Editing via Control Handle Transformations
Yue Ma, Xiaodong Cun, Yingqing He, Chenyang Qi, Xintao Wang, Ying Shan, Xiu Li, Qifeng Chen WACV, 2025 Project Page / Paper / Github
|
|
|
Freenoise: Tuning-free longer video diffusion via noise rescheduling
Haonan Qiu, Menghan Xia, Yong Zhang, Yingqing He, Xintao Wang, Ying Shan, Ziwei Liu ICLR, 2024 Project Page / Paper / Github
|
|
|
Follow your pose: Pose-guided text-to-video generation using pose-free videos
Yue Ma*, Yingqing He*, Xiaodong Cun, Xintao Wang, Siran Chen, Ying Shan, Xiu Li, Qifeng Chen AAAI, 2024 Project Page / Paper / Github
|
|
|
Make-Your-Video: Customized Video Generation Using Textual and Structural Guidance
Jinbo Xing, Menghan Xia, Yuxin Liu, Yuechen Zhang, Yong Zhang, Yingqing He, Hanyuan Liu, Haoxin Chen, Xiaodong Cun, Xintao Wang, Ying Shan, Tien-Tsin Wong TVCG, 2024 Project Page / Paper Given text description and video structure (depth), our approach can generate temporally coherent and high-fidelity videos. Its applications include dynamic 3d-scene-to-video creation, real-life scene to video, and video rerendering. |
|
|
TaleCrafter: Interactive Story Visualization with Multiple Characters
Yuan Gong, Youxi Pang, Xiaodong Cun, Menghan Xia, Yingqing He, Haoxin Chen, Longyue Wang, Yong Zhang, Xintao Wang, Ying Shan, Yujiu Yang SIGGRAPH Asia, 2023 Project Page / Paper / Github
|
|
|
Videocrafter1: Open diffusion models for high-quality video generation
Haoxin Chen*, Menghan Xia*, Yingqing He*, Yong Zhang, Xiaodong Cun, Shaoshu Yang, Jinbo Xing, Yaofang Liu, Qifeng Chen, Xintao Wang, Chao Weng, Ying Shan Technical Report, 2023 Project Page / Paper / Github An open-sourced foundational text-to-video and image-to-video diffusion model for high-quality video generation. |
|
Latent Video Diffusion Models for High-Fidelity Long Video Generation
Yingqing He, Tianyu Yang, Yong Zhang, Ying Shan, Qifeng Chen Technical Report, 2022 Project Page / Paper / Github
|
|
|
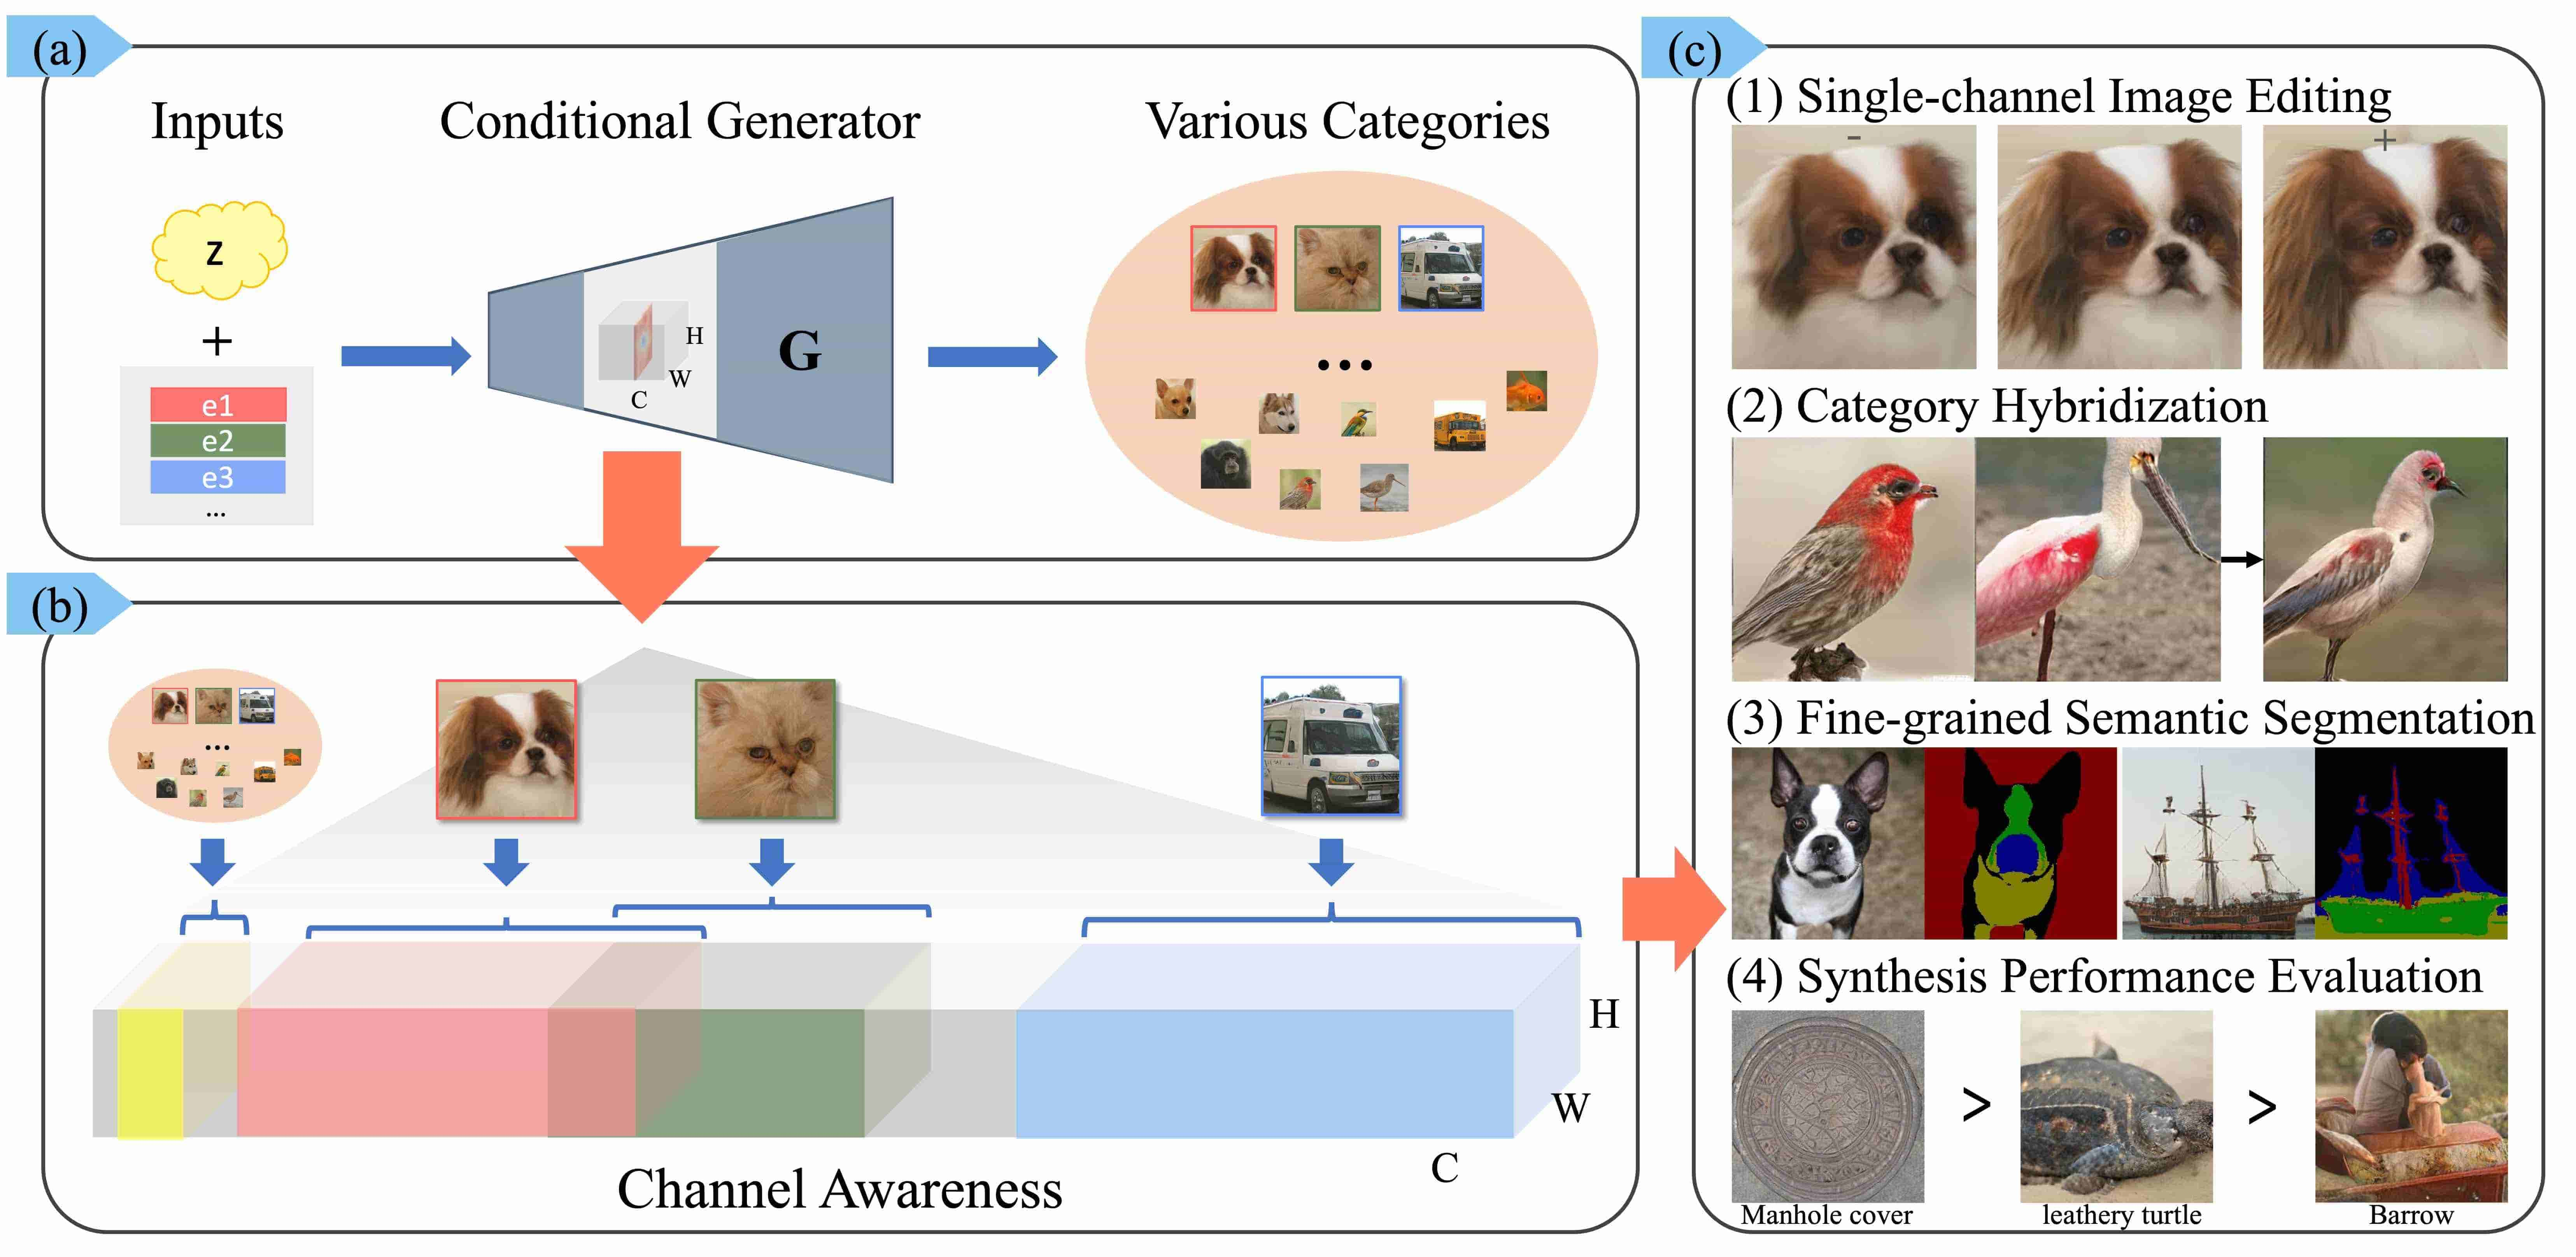
Interpreting class conditional GANs with channel awareness
Yingqing He, Zhiyi Zhang, Jiapeng Zhu, Yujun Shen, Qifeng Chen Technical Report, 2022 Project Page / Paper / Github
|
|
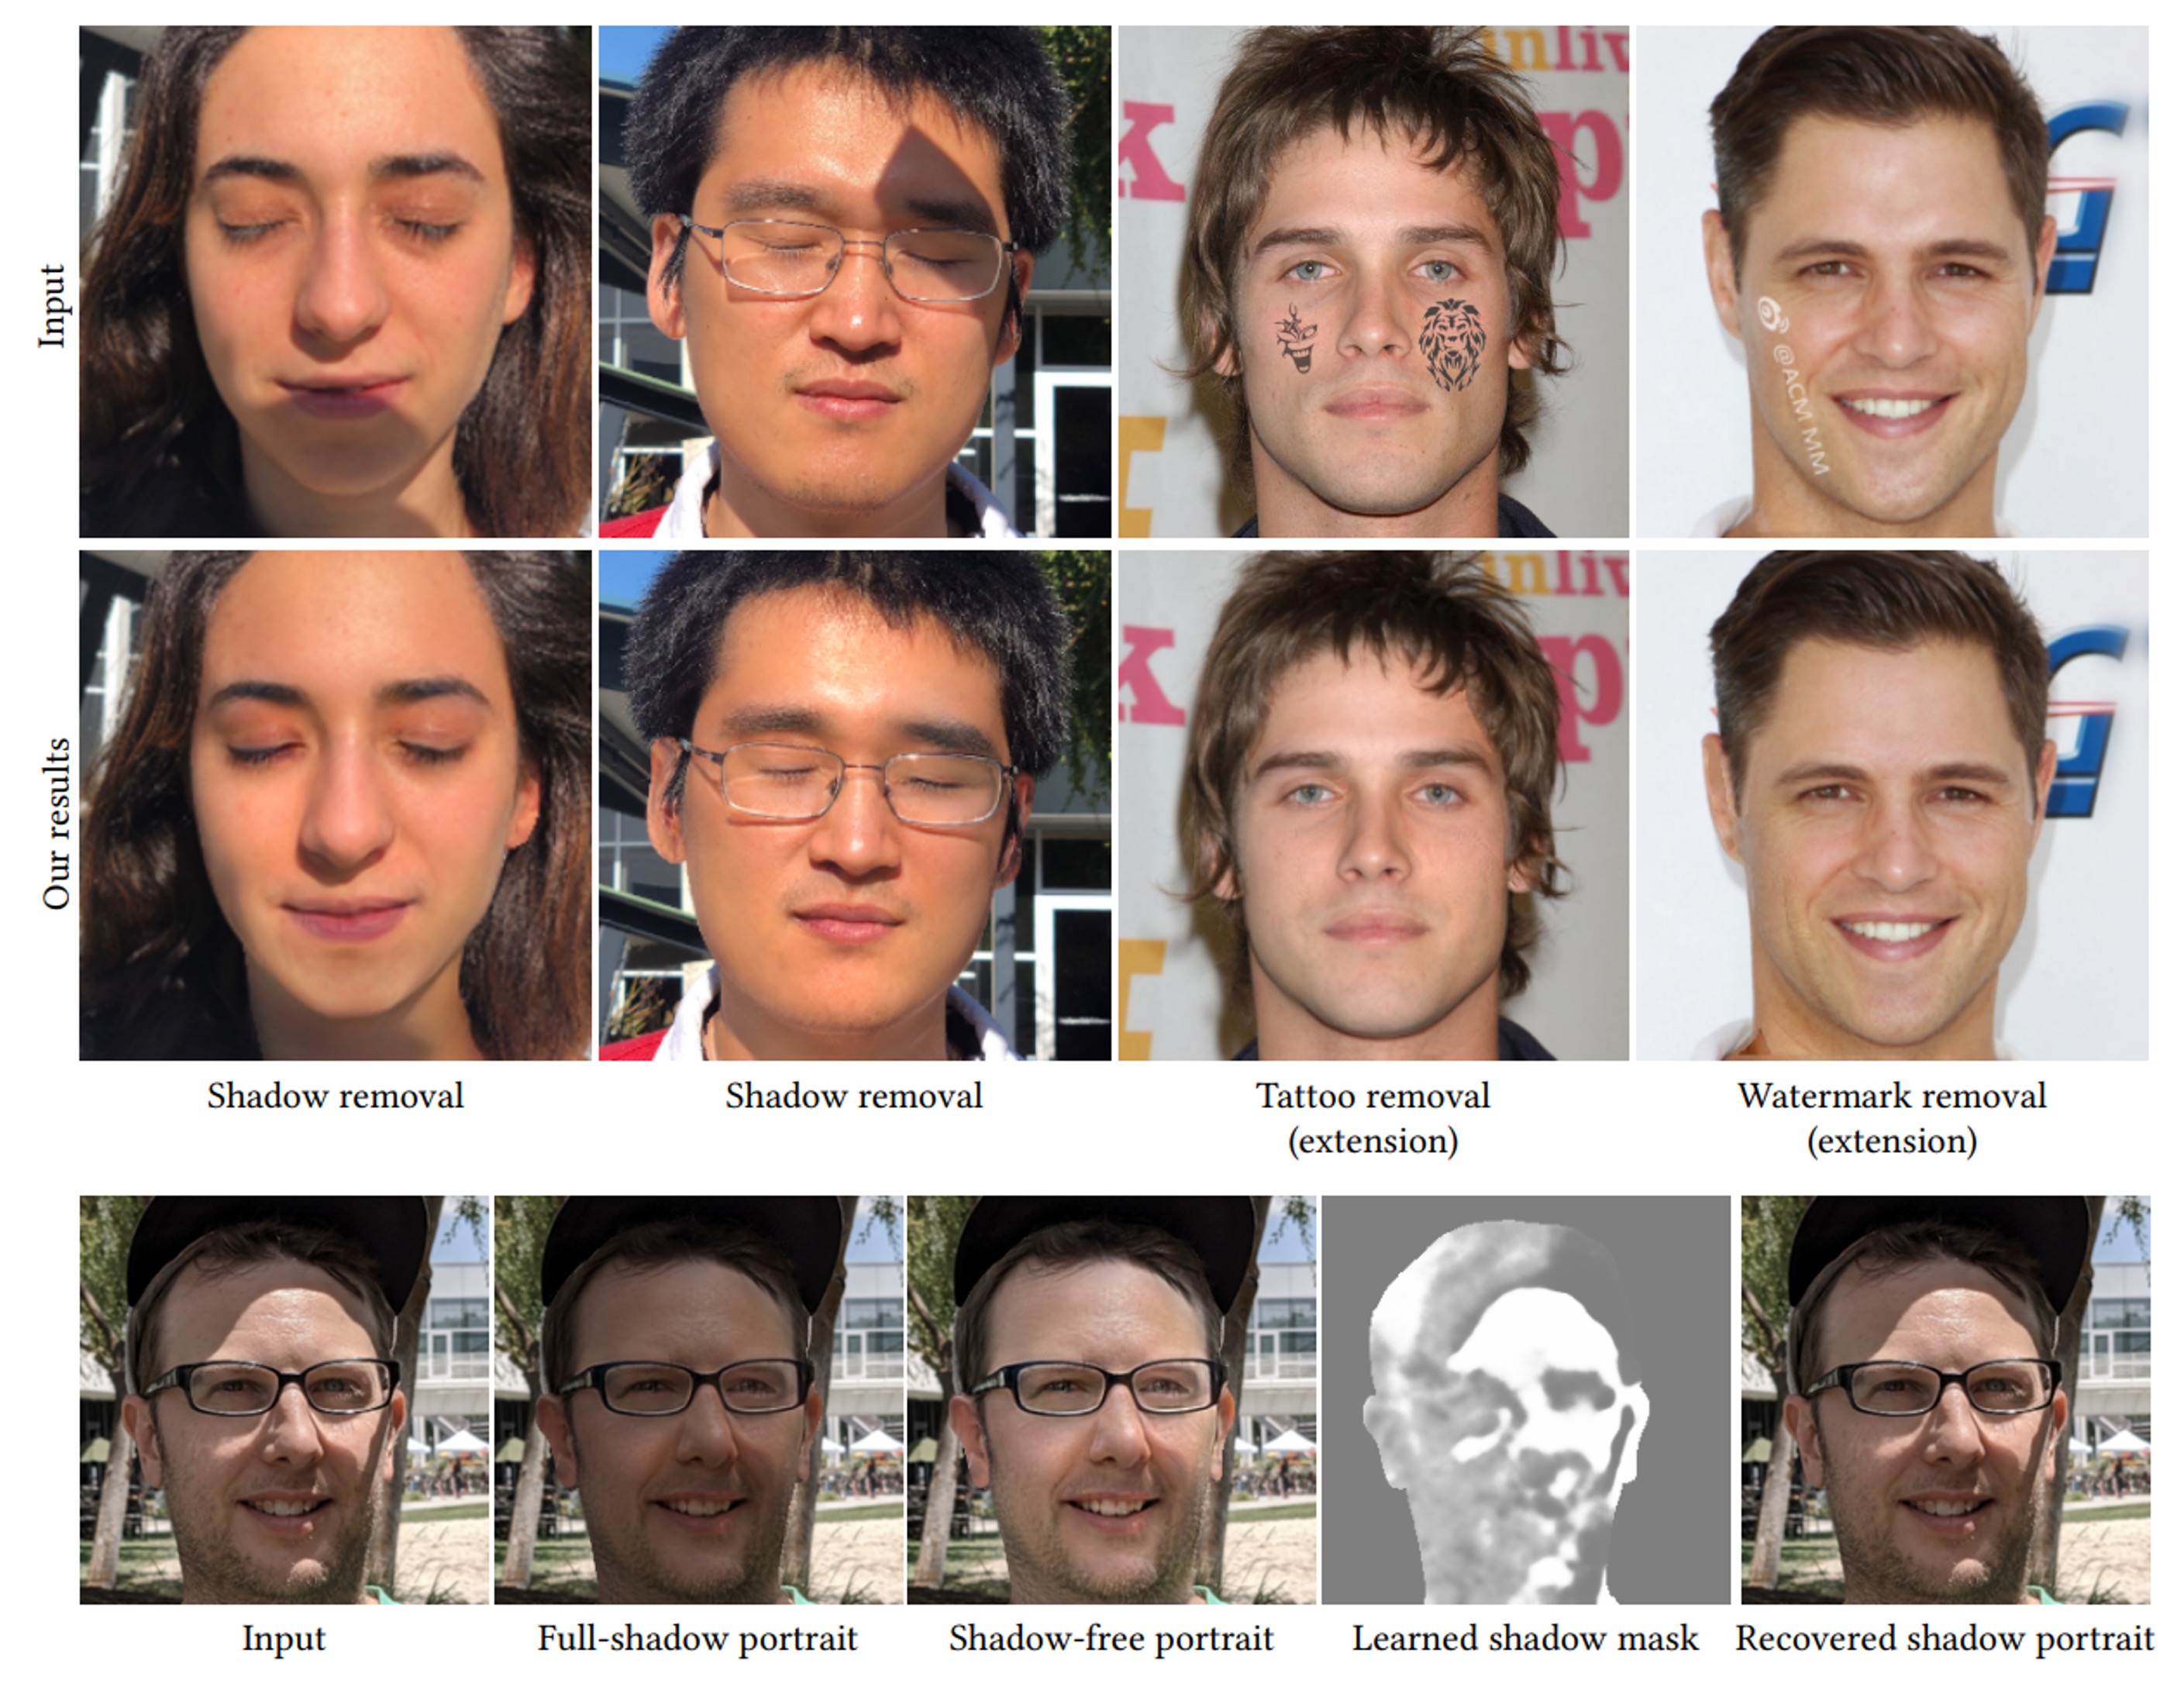
Unsupervised portrait shadow removal via generative priors
Yingqing He*, Yazhou Xing*, Tianjia Zhang, Qifeng Chen ACM MM, 2021 (Oral) Paper / Github we propose an unsupervised method for portrait shadow removal, leveraging the facial priors from StyleGAN2. Our approach also supports facial tattoo and watermark removal. |
Internships
|
Academic Services
|
|
Webpage templete is borrowed from this |